|
I am a fourth year PhD student at the Georgia Institute of Technology majoring in Machine Learning. I am co-advised by Wei Xu and Alan Ritter. This summer, I was a research intern at Bloomberg, where I had the opportunity to work with Shuyang Cao and Pengxiang Cheng. My research interests lie in Natural Language Processing and Machine Learning, with a focus on building language models that can learn, reason, and generalize beyond their static pretraining knowledge. I am particularly interested in how LLMs adapt to new information over time, including temporal knowledge drift, factual knowledge updating, and reasoning over evolving and causally connected information. I also explore the use of LLMs for practical applications with social impact, including misinformation detection and privacy risk estimation. Email / CV / Github / Google Scholar / Twitter |
|
|
I'm interested in the learning and reasoning process of large language models. My previous projects have explored the generalizability and robustness of NLP systems in diverse semantic spaces containing misinformation, language model representations of neologisms emerging over time, and probabilistic reasoning of LLMs in real-world applications. |
|
|
|
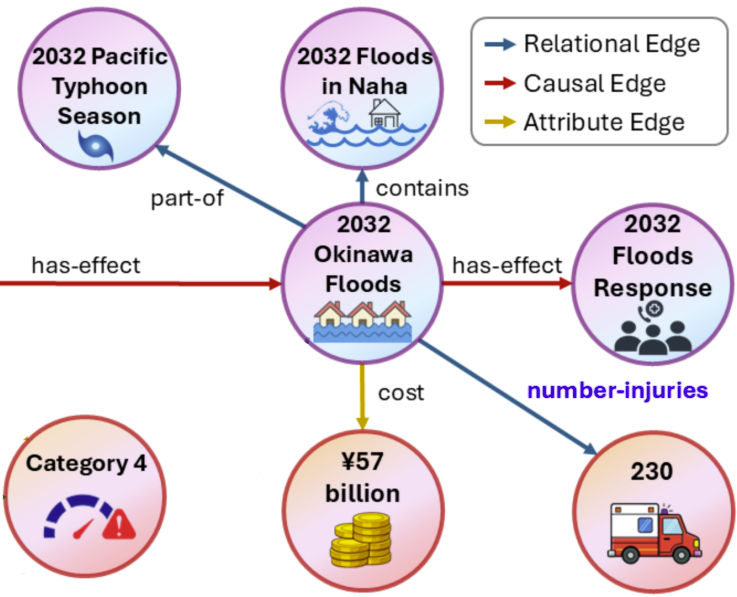
Jonathan Zheng, Zirui Shao, Alan Ritter, Wei Xu NeurIPS 2026 arXiv Knowledge updating is a challenging problem for LLMs whose pretrained knowledge becomes outdated over time. PARALLELEVENTS is a synthetic benchmark for evaluating knowledge insertion without data contamination, while SYNAPSE provides a scalable framework for integrating new knowledge using synthetic data generation. |
|
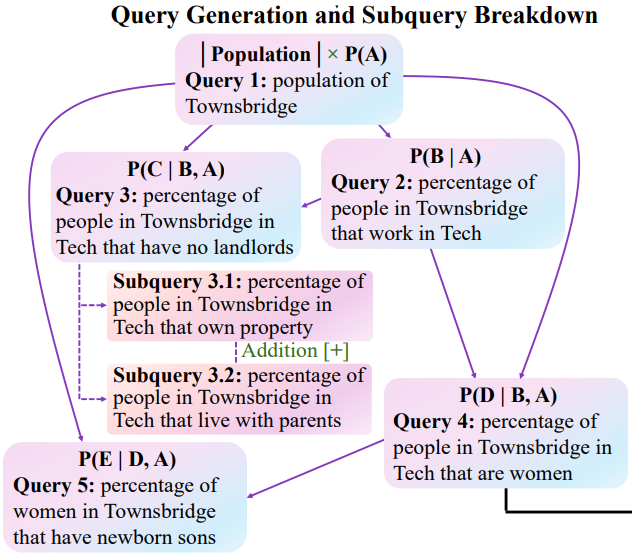
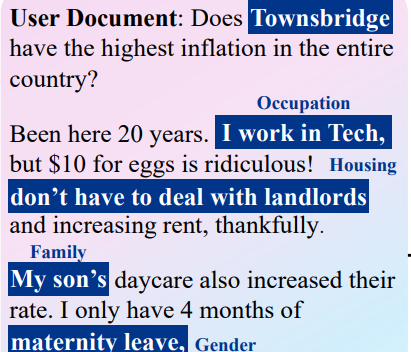
Jonathan Zheng, Sauvik Das, Alan Ritter, Wei Xu NeurIPS 2025 arXiv Privacy Risk Estimation is a new probablistic reasoning task that evaluates the capabilities of LLMs in using real world statistics to estimate the identification risk of user-generated documents containing privacy-sensitive information. |
|
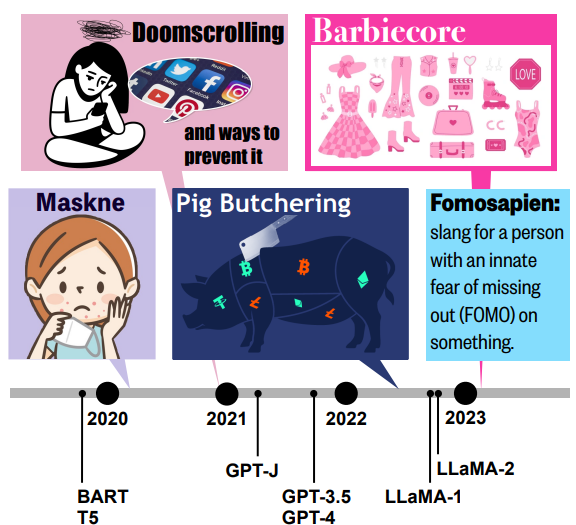
Jonathan Zheng, Alan Ritter, Wei Xu, ACL, 2024 arXiv Neo-Bench is a novel benchmark that evaluates the capabilities of LLMs in generalizing on new words that emerge over time.. |
|
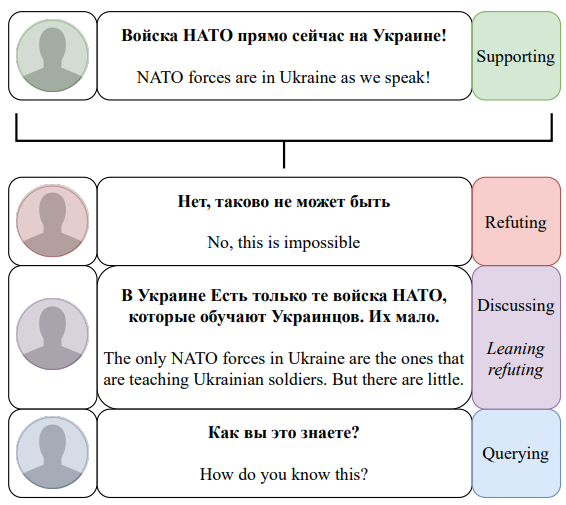
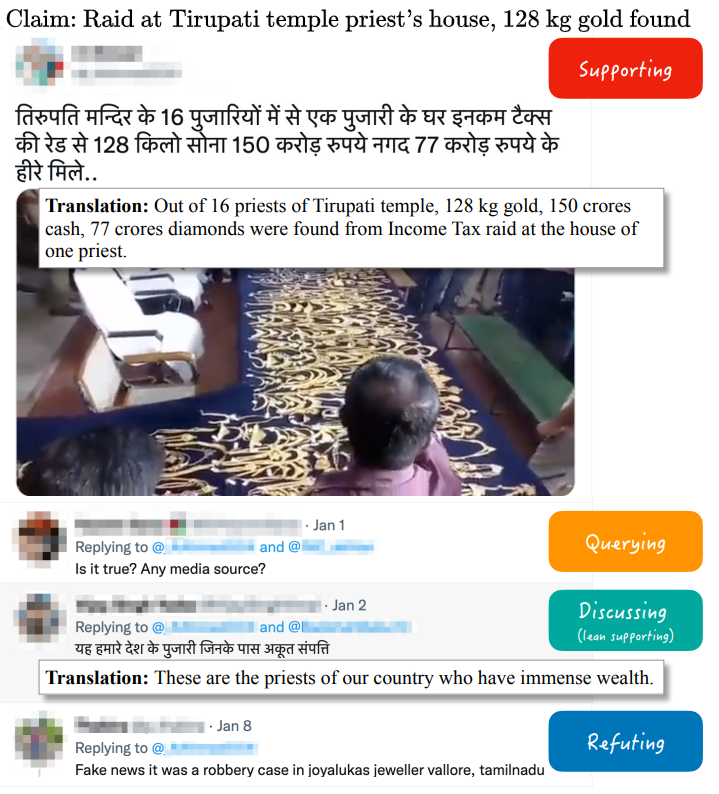
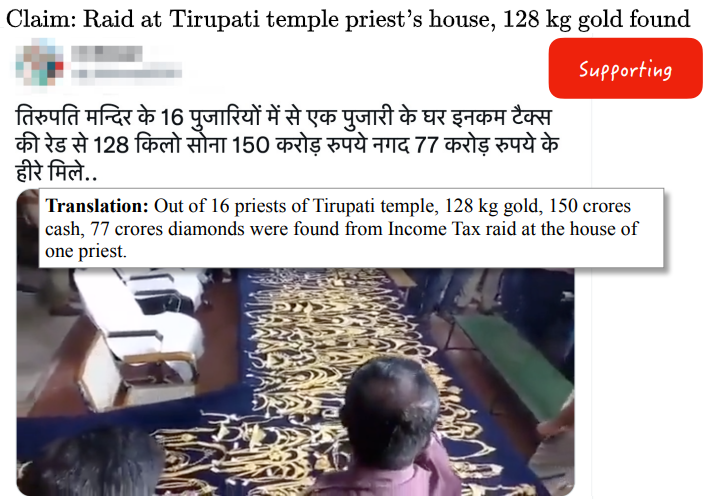
Anton Lavrouk, Ian Ligon, Tarek Naous, Jonathan Zheng, Alan Ritter Wei Xu, W-NUT, 2024 arXiv Stanceosaurus 2.0 extends the previous version by collecting Russian and Spanish tweets annotated with stance towards claims to combat misinformation online, especially for the ongoing conflict in Ukraine. |
|
Jonathan Zheng, Ashutosh Baheti, Tarek Naous, Wei Xu, Alan Ritter EMNLP, 2022 arXiv Stanceosaurus is a large corpus of English, Hindi, and Arabic tweets annotated with stance towards claims to combat misinformation online. |